The Real-Time Illusion: Why Faster Data Isn't Always Smarter Data for Enterprise Decision-Making
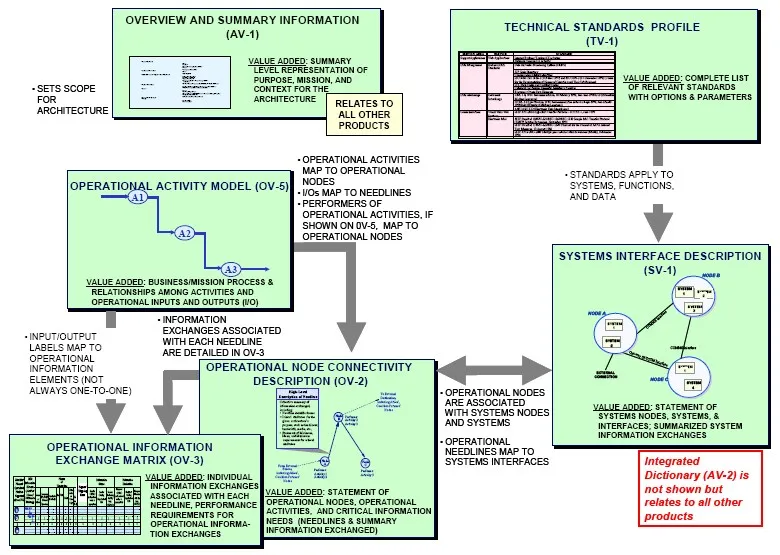
Photo: DoD Architecture Framework Working Group, Public domain, via Wikimedia Commons
Ask any enterprise software vendor to describe their data architecture, and the word "real-time" will appear within the first two sentences. It has become the default selling point, the assumed north star, the architectural aspiration that no self-respecting platform can afford to omit from its marketing materials.
But spend enough time talking to the architects who actually build and maintain these systems — the ones responsible for keeping them running at 2 a.m. when something breaks — and a more complicated picture emerges. Real-time processing is not universally superior. Batch processing is not obsolete. And the organizations that have treated this as a settled question are, in many cases, operating infrastructure that is significantly more expensive and complex than their actual decision-making requirements justify.
This piece argues for a more deliberate framework — one that treats the real-time versus batch question as a genuine architectural decision rather than an ideological one.
What We Actually Mean by Real-Time
Before the comparison can be made honestly, the terminology requires scrutiny. "Real-time" in enterprise contexts is rarely literal. What most platforms deliver is more accurately described as near-real-time or low-latency streaming — data that is processed and available within seconds or minutes rather than milliseconds. True real-time processing, at the latency required for applications like algorithmic trading or autonomous vehicle navigation, is a distinct engineering discipline with cost and complexity profiles that are irrelevant to most enterprise intelligence use cases.
Batch processing, by contrast, involves collecting data over a defined period and processing it as a group — hourly, nightly, or on a scheduled cadence. The architecture is simpler, the infrastructure costs are substantially lower, and the failure modes are more predictable and easier to recover from.
The meaningful question for most enterprise organizations is not "real-time or batch?" but rather: "How fresh does this data need to be for the decision it is supporting?"
The Case for Real-Time: Where It Genuinely Delivers
There are enterprise use cases where low-latency data processing is not a luxury but a functional requirement.
Fraud detection is the canonical example. Financial institutions processing card transactions must evaluate each transaction against behavioral models within milliseconds of authorization. A batch architecture that processes transactions hourly would render fraud detection essentially useless — by the time the anomaly is flagged, dozens of fraudulent transactions would have already cleared.
Customer-facing personalization at scale is another legitimate real-time domain. E-commerce platforms that surface product recommendations based on in-session behavior — what a user has clicked, searched, and lingered on in the past five minutes — require streaming data pipelines to function. A nightly batch process cannot support that use case.
Operational monitoring in manufacturing and logistics is a third category where real-time architecture earns its cost. Sensor data from production equipment, when processed continuously, can trigger predictive maintenance alerts before a failure occurs. The same data processed in hourly batches arrives too late to prevent the downtime it was meant to anticipate.
In each of these cases, the business value of low latency is direct, measurable, and sufficient to justify the additional infrastructure investment.
The Case Against Real-Time: Where the Industry Has Oversold
Outside of those categories, the evidence for real-time as a universal standard becomes considerably weaker.
Enterprise architects interviewed for this piece — representing organizations in healthcare, financial services, and manufacturing — described a recurring pattern: real-time pipelines implemented at significant cost and complexity to support use cases that, on examination, did not require data fresher than an hour or a day.
"We built a streaming architecture for our executive reporting dashboards," said one senior data architect at a Fortune 200 manufacturing company, speaking on background. "The executives look at those dashboards once a day, in the morning. We were paying for infrastructure to keep that data current to the minute for an audience that was never going to benefit from it."
This misalignment between data latency and decision cadence is more common than the industry acknowledges. Strategic planning processes operate on weekly or monthly cycles. Financial consolidation runs on quarterly rhythms. Workforce analytics rarely require sub-hour data freshness. For these use cases, the operational overhead of a streaming architecture — the additional engineering expertise required, the higher failure surface area, the increased cloud compute costs — represents a genuine waste of organizational resources.
A 2022 analysis by Gartner estimated that enterprises operating streaming architectures for batch-appropriate workloads spend an average of 40 percent more on data infrastructure than organizations that match their architecture to their actual latency requirements.
A Framework for Architectural Decisions
Rather than defaulting to real-time as the aspirational standard, enterprise architects would be better served by a structured evaluation framework built around three questions.
First: What is the decision this data supports, and how frequently is that decision made? If the answer is "daily" or "weekly," a batch architecture almost certainly provides sufficient freshness. If the answer is "continuously" or "within seconds of an event," streaming becomes a legitimate requirement.
Second: What is the cost of data staleness? In fraud detection, stale data enables financial loss. In a monthly sales performance report, data that is 12 hours old is operationally equivalent to data that is 12 minutes old. Quantifying this cost explicitly forces a more honest conversation about what the architecture actually needs to deliver.
Third: What is the total cost of ownership, including operational complexity? Streaming architectures require specialized engineering skills, more sophisticated monitoring, and more complex failure recovery procedures. These costs are real and should be weighed against the business value of lower latency.
The Hybrid Architecture Reality
In practice, the most effective enterprise data platforms are neither purely real-time nor purely batch — they are hybrid architectures that apply the appropriate processing model to each workload based on its actual requirements.
The Lambda architecture pattern, which maintains separate batch and streaming processing layers that feed a unified serving layer, has been widely adopted precisely because it acknowledges this reality. More recent approaches, including the Kappa architecture and various implementations built on platforms like Apache Kafka and Apache Flink, offer different trade-offs between simplicity and flexibility.
What these patterns share is a rejection of the premise that one processing model should dominate all workloads. They treat real-time and batch as complementary tools rather than competing philosophies.
The Organizational Dimension
Architecture decisions do not happen in a vacuum. The bias toward real-time in enterprise technology is partly a product of vendor incentives — streaming platforms command premium pricing and generate ongoing infrastructure revenue — and partly a product of the status dynamics within engineering organizations, where real-time systems are perceived as more technically sophisticated and therefore more professionally prestigious.
Challenging that bias requires enterprise leaders to create an environment where architectural decisions are evaluated on business outcomes rather than technical impressiveness. The question to ask is not "Is our data pipeline real-time?" but "Is our data architecture producing better decisions at a justifiable cost?"
For most enterprise intelligence use cases, the honest answer to that question does not require a streaming architecture. It requires a thoughtful one.